Best Mac for Local LLM Inference (2026): The Unified-Memory Buying Guide
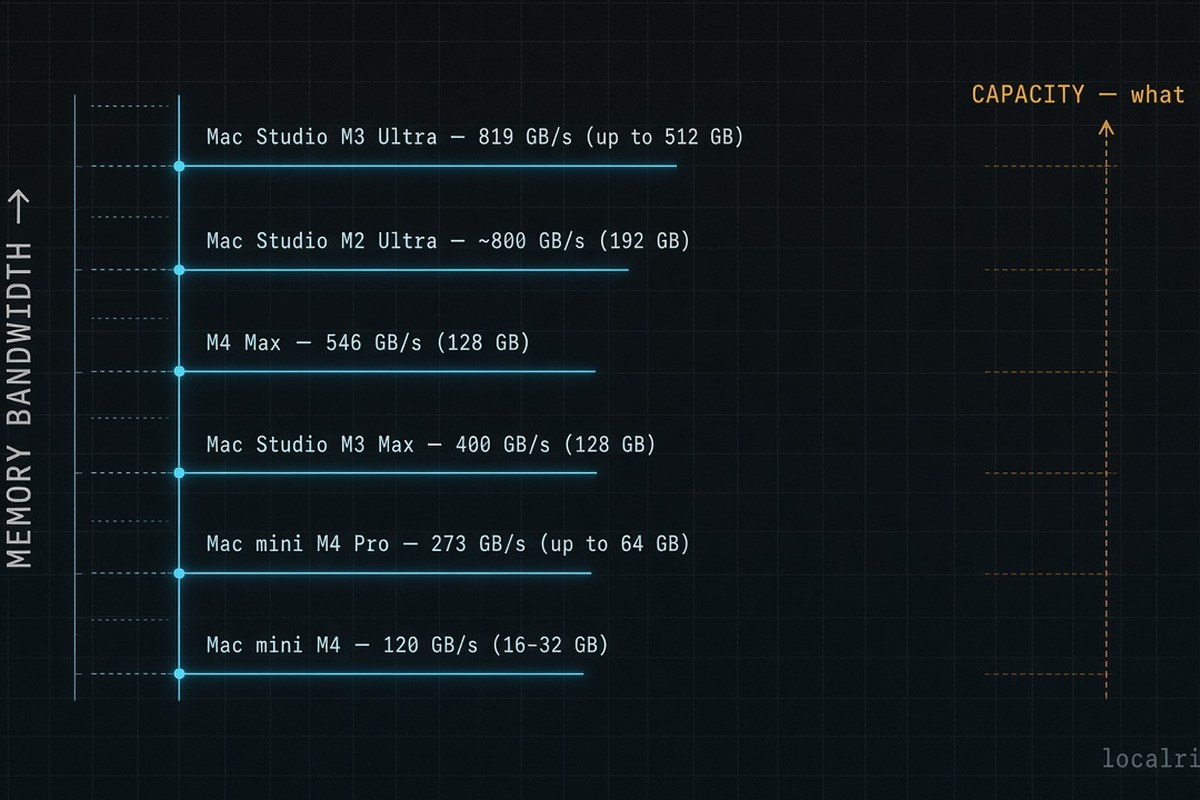
A Mac is a genuinely good local-AI machine for one specific reason: unified memory. The CPU and GPU share one pool, so a Mac can hold models that do not fit in a consumer GPU’s VRAM, in a quiet box that sips power. But “more memory” is only half the story. Two specs decide whether a Mac is right for you, and they pull in different directions.
October 6, 2026: Apple has sold Mac Studio with M5 Max and M5 Ultra, and Mac mini with M6 and M5 Pro, since September 22, 2026. New Studio configuration choices — memory tier, 614GB/s versus 1.2TB/s, and list price — are on the M5 Max and M5 Ultra configuration guide. The ladder below is the June 28, 2026 M4/M3 map. Its tok/s rows are M4, M3, and earlier. They are not M5 measurements. LocalRig has not measured M5 tokens per second.
Parent guide: The Local-AI Hardware Buying Framework. If you are weighing a Mac against an NVIDIA card, read this alongside the best GPU for local LLM guide.
The two specs that decide a Mac for local AI
- Unified memory capacity decides what fits. A 70B model at Q4 needs ~40 GB; a 128 GB Mac holds it with room to spare, where a 24 GB GPU cannot fit it at all. This is Apple’s superpower.
- Memory bandwidth decides how fast it decodes. Token generation is memory-bandwidth-bound — every token re-reads the model weights — so bandwidth, not core count, tracks tokens per second most closely.
The trap is treating those as one number. A big-memory Mac will fit a model a GPU can’t, and still decode it slower than that GPU would if the model fit. Capacity is not speed. The capacity math is in What Is Quantization; the bandwidth reasoning sits behind every row of the table below.
The M-series ladder (ordered by bandwidth)
Bandwidth — not the chip’s marketing name — is the axis that predicts decode speed, so the table is ordered that way. tok/s figures are for Llama 3.1 8B Q4_K_M.
| Mac | Unified memory | Bandwidth | 8B Q4 tok/s | Source |
|---|---|---|---|---|
| Mac mini M4 (base) | 16 / 24 / 32 GB | ~120 GB/s | 18.4 (llama.cpp) / 19.5 (Ollama) | LocalRig first-party, 16 GB, 2026-06-27 |
| Mac mini M4 Pro | up to 64 GB | ~273 GB/s | ~30–50 | community (r/LocalLLaMA, 2025) |
| Mac Studio M3 Max | 96 / 128 GB | ~400 GB/s | ~50–65 | community (2025) |
| Mac Studio / MBP M4 Max | up to 128 GB | ~546 GB/s | — (not yet benchmarked) | spec; expect > M3 Max |
| Mac Studio M2 Ultra | up to 192 GB | ~800 GB/s | ~70–80 | community (Simon Willison, 2024–25) |
| Mac Studio M3 Ultra | up to 512 GB | ~819 GB/s | — (not yet benchmarked) | spec; top consumer tier |
Read the pattern, not just the rows: as bandwidth climbs from ~120 to ~800 GB/s, 8B throughput climbs with it. Only the base M4 row is LocalRig-measured; the rest are community-cited or spec-derived and labeled as such. The two “not yet benchmarked” rows are flagged honestly — a first-party M-series sweep is queued and will land on the benchmarks page.
Why capacity is the reason to buy Apple
Where Apple Silicon wins decisively is the model that simply will not fit on a normal GPU. A 70B at Q4 (~40 GB) fits on a 128 GB Mac; a 512 GB M3 Ultra holds models no consumer GPU stack can touch without sharding across several cards. You get that in one silent box drawing tens of watts, with no multi-GPU topology to manage. For the 70B decision specifically, see Hardware to Run a 70B Model Locally.
The cost of that capacity is bandwidth. A Mac’s unified memory feeds the GPU more slowly than a discrete card’s dedicated GDDR6X or HBM, so when a model also fits on an NVIDIA card, the card decodes faster. A used RTX 3090 will out-token a similarly-priced Mac on an 8B model — the Mac earns its price when the model is too big for 24 GB, or when silence, power, and a single-box footprint matter more than raw speed.
Runtime on a Mac
Use MLX (Apple’s native framework) for the best Mac-native path, with llama.cpp as the portable GGUF fallback — both use Metal. We do not route readers to Ollama: it wraps llama.cpp with the same kernels and opaque defaults, so you gain nothing on speed and lose control. The full reasoning is in How to Run LLMs Locally.
The picks
- Entry / “can I even do this”: Mac mini M4 (base). The cheapest way into Apple Silicon inference, around 19 tok/s on an 8B at Q4 (LocalRig-measured). Get the 24 GB configuration, not 16 GB — the base 16 GB is tight once the OS and a working context are accounted for. Mac mini M4 on Amazon →
- Best value: Mac mini M4 Pro. The jump from ~120 to ~273 GB/s is the upgrade that actually shows up in tokens per second, and the 64 GB option opens 32B and even 70B-class models. This is the Mac most local-AI buyers should look at first. Mac mini M4 Pro on Amazon →
- Big models, one quiet box (current new buy): Mac Studio M5 Max or M5 Ultra, on sale since September 22, 2026. Capacity now runs through 128GB on M5 Max and 256GB (512GB in late October) on M5 Ultra. Specs, list prices, and the empty M5 tok/s cell are on the configuration guide. M5 Max on Amazon →
- Prior-generation capacity: Mac Studio M3 Ultra, covered on its own page. The ~819 GB/s and “up to 512 GB” line in the table below is that older spec, not the M5 sheet. M3 Ultra on Amazon →
- Laptop that also runs big models: MacBook Pro M4 Max. The only laptop class with both the bandwidth (~546 GB/s) and the memory to run large models away from a desk. MacBook Pro M4 Max on Amazon →
Decision matrix
| Your situation | Pick | Why |
|---|---|---|
| Trying local AI for the first time | Mac mini M4 (24 GB) | Lowest-cost entry; ~19 tok/s on 8B |
| Most buyers: value + room to grow | Mac mini M4 Pro (64 GB) | The bandwidth step that matters; fits 32B–70B |
| 70B+ models, silence, one box, bought new after 2026-09-22 | M5 Max 128GB or M5 Ultra | See the configuration guide; this table is the pre-M5 ladder |
| Need a laptop | MacBook Pro M4 Max | Only portable with the bandwidth + capacity |
| Model fits in 24 GB and you want speed | A used RTX 3090 instead | Faster decode per dollar — see the GPU guide |
Who This Is NOT For
- Anyone who needs maximum tokens per second or concurrency. On models that fit a 24 GB GPU, an NVIDIA card decodes faster and serves more parallel requests. If raw throughput is the priority, start at the best GPU guide.
- Buyers whose model fits in 24 GB on a budget. A used RTX 3090 is cheaper and faster for 7B–13B work; the Mac justifies its price when the model exceeds consumer VRAM.
- Fine-tuners and trainers. This is an inference guide. Most training frameworks assume CUDA, and the memory math for training is very different.
- People chasing the cheapest possible box. The base Mac mini M4 is a real entry point, but if “cheapest interactive 8B” is the only goal, compare it honestly against a used GPU before buying.
Sources
- LocalRig first-party benchmark: base Apple M4 (16 GB) — llama.cpp b9820 (18.4 tok/s) and Ollama 0.30.11 (19.5 tok/s), Llama 3.1 8B Q4_K_M, 2026-06-27. See the 7B/8B guide for methodology.
- LocalRig knowledge note, “Memory Bandwidth for Local AI Hardware (2026)” — the M-series bandwidth ladder.
- r/LocalLLaMA Apple Silicon benchmark threads (2024–2025) and Simon Willison’s documented M2 Ultra benchmarks — community throughput, explicitly not independently verified by LocalRig.
- Apple M-series unified memory and bandwidth specifications, apple.com.
Frequently Asked Questions
Which Mac should I buy to run local LLMs?
For a Mac Studio ordered after September 22, 2026, use the M5 Max and M5 Ultra configuration guide. This page's ladder is the June 28, 2026 M4 and M3 map and was not re-priced on October 6. Memory capacity and memory bandwidth are still two specs.
Will a Mac beat an RTX 4090 on tokens per second?
Usually no, on models that fit in 24 GB. The Mac wins when the model does not fit in GPU VRAM at all. LocalRig first-party: base M4 16 GB ran Llama 3.1 8B Q4 at 18.4–19.5 tok/s (2026-06-27).
How much unified memory for 70B?
64 GB is the nervous minimum at Q4; 128 GB is the comfortable buy. Bandwidth still caps decode speed — a big, slow Mac is a capacity machine, not a tok/s machine.
Who should not buy a Mac for local AI?
Anyone whose workload is fine-tuning, high-batch serving, or CUDA-only tooling (vLLM, TensorRT-LLM). Buy NVIDIA or rent.