Hardware to Run a 70B Model Locally: VRAM, the 48GB Wall, and Your Real Options
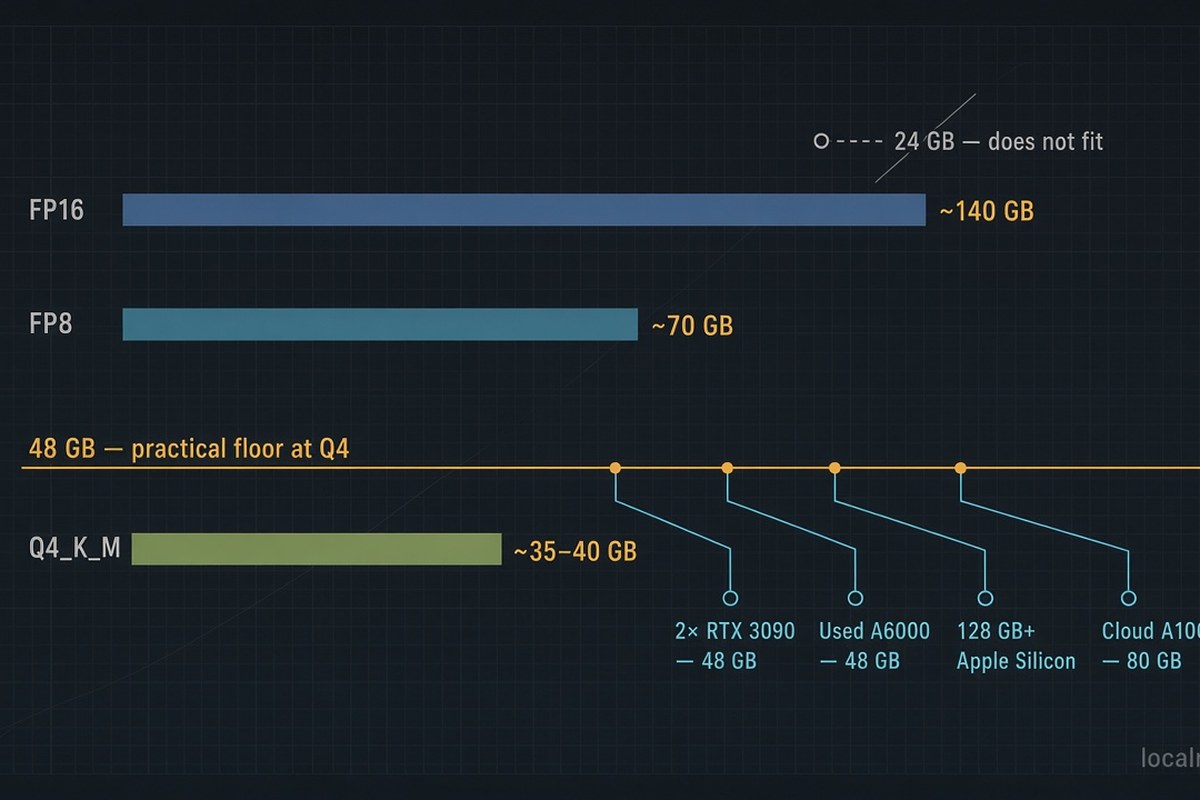
A 70B model is the first size class where the hardware decision stops being “which GPU” and becomes “which architecture.” A 7B model fits almost anywhere; a 70B model does not fit in a single consumer GPU at usable quality, so you are choosing between multiple GPUs, a large unified-memory Mac, a turnkey DGX Spark appliance, or renting. This guide gives you the VRAM math, the practical floor, and the five real paths — with honest notes on where the data is solid and where it is not.
Parent guide: The Local-AI Hardware Buying Framework — read the constraint logic first. For the smaller class, see Hardware to Run a 7B/8B Model Locally.
The VRAM math for 70B
The sizing rule is simple and it is the whole game at this size: VRAM (GB) ≈ parameters (billions) × (bits per weight ÷ 8), then add overhead. For a 70B model:
| Precision | Weights only | Practical total (weights + KV cache + overhead) |
|---|---|---|
| FP16 (full) | ~140 GB | ~150–170 GB |
| FP8 / INT8 | ~70 GB | ~80–90 GB |
| Q4_K_M (4-bit) | ~35–40 GB | ~44–52 GB |
| Q3 / Q2 (aggressive) | ~26–33 GB | ~34–44 GB (quality cost rises) |
Two things follow immediately. First, 24GB is not enough for a 70B model at usable quality — even Q4_K_M weights alone (~35–40 GB) exceed a single 3090 or 4090. Second, 48GB is the practical floor at Q4: it holds the weights plus a working KV cache and runtime overhead with a little room. Weights are only part of the bill — the KV cache grows with context length and will eat the headroom at long contexts, so budget the 10–30% overhead band, more if you run 32K+ context. The full reasoning is in What Is Quantization and the GPU memory math section of the framework.
Quantization at 70B: Q4_K_M is the sweet spot. Larger models degrade more gracefully under quantization than small ones, so a 70B at Q4 generally beats a 34B at Q8 for the same memory budget. Go below Q4 (Q3/Q2) only when you must squeeze into a tighter pool and you have tested that the quality still serves your use case.
A note on throughput data
A 70B model decodes far more slowly than a 7B one because decode is memory-bandwidth-bound and you are now moving ~40 GB of weights per token instead of ~4 GB. Community reports put 70B Q4 generation in the low-double-digit tokens-per-second range on both dual-3090 rigs and large Apple Silicon — but those numbers vary widely with quant, context, runtime, and interconnect, and LocalRig has not yet measured 70B first-party. Treat any specific figure below as a community range, not a LocalRig benchmark; a first-party 70B run is queued, and verified numbers will land on the benchmarks page. The fit math above is the part you can plan around with confidence; throughput is the part to verify for your exact setup.
The five paths
Path A — 2× used RTX 3090 (48GB total)
The community’s standard 70B rig. Two used 3090s give you 48 GB of fast GDDR6X, and llama.cpp, ExLlamaV3, and vLLM all split a 70B across both cards (tensor or pipeline parallel). CompSniper, fetched 6 October 2026, reports a sold median of $1,499 per card across 204 recent eBay sales, most of them $1,329–$1,599, latest sale 6 October 2026. 2 × that median is $2,998 in cards. That is arithmetic, not a paired sold listing, and it does not include shipping (the page says about $19), a PSU, a board, or a case. RigPrice lists a used asking rate of $1,655 on 2026-10-06 ($1,665 on 2026-10-04). The old $1,000–$1,600 pair band is retired. The catch is interconnect: without NVLink, the cards talk over PCIe, so you do not get 2× the speed of one card — multi-GPU here buys capacity (the model fits), not linear throughput. Plan PSU and cooling for two ~300–350W cards. $2,998 in cards is still under a 64GB Spark from $4,999 and the reported $6,950 128GB list. It is not more advertised memory per dollar than that 128GB box.
Browse used RTX 3090 on eBay → · for the single-card reasoning behind this pick, see the best GPU for local LLM guide.
Path B — single used RTX A6000 (48GB)
One card, 48 GB, no multi-GPU split to manage, and far lower power than two 3090s. The A6000 (Ampere, 48GB) is the simplest way to hold a 70B Q4 in a single device, and the used/refurbished enterprise market is where it is affordable. You give up some raw bandwidth versus a 4090-class card, but you gain capacity and simplicity. Browse used A6000 on eBay →
Path C — Apple Silicon with 128GB+ unified memory
A Mac Studio or MacBook Pro with 128 GB (M3/M4 Max) or 192 GB (M2 Ultra) holds a 70B Q4 comfortably — 40 GB out of a much larger shared pool — while drawing a fraction of the power of a dual-GPU rig and staying quiet. The tradeoff is bandwidth: unified memory feeds the GPU more slowly than dedicated GDDR6X or HBM, so decode is capacity-rich but not the fastest. This is the path if you also want a low noise floor, low power, or a laptop form factor, or if you intend to step up to even larger models later. Check Mac Studio configurations on Amazon →
Path D — NVIDIA DGX Spark, when you want a turnkey appliance
DGX Spark is the “buy the NVIDIA box” path: 128GB unified LPDDR5x, a GB10 Grace Blackwell chip, DGX OS, and 4TB NVMe in a compact desktop. It has enough memory headroom for a 70B Q4 model without the parts-list complexity of a dual-3090 workstation or the Apple-specific runtime tradeoffs of a Mac. The tradeoff is price and freshness: LocalRig has not benchmarked DGX Spark yet, so this is a fit-and-software-stack recommendation, not a tokens-per-second claim.
Spark price note (2026-10-06). A 64GB OEM configuration was announced on 2026-10-02, shipping 23 October from $4,999. The Register reported the 128GB list at $6,950 the same day. The older “$3,999+” Spark figure is not the October 2026 price. Which SKU fits a 70B Q4 versus a larger checkpoint is DGX Spark 64GB vs 128GB. The used-3090 dollars on this page are CompSniper’s 6 October 2026 per-card median, not the old $1,000–$1,600 pair band. NVIDIA DGX Spark on Amazon → · DGX Spark 2-pack bundle on Amazon →
Path E — cloud, when 70B is occasional
If you need a 70B only now and then, renting an 80GB A100/H100 by the hour can beat buying a 48GB rig outright — especially before you have validated that local is worth it. Run the honest break-even before committing hardware: see the Local vs Cloud cluster. (Cloud-GPU referral programs are not yet wired into LocalRig, so this is guidance, not a monetized link.)
Decision matrix
| Your situation | Path | Why |
|---|---|---|
| 48GB split, and you can build the rig | 2× used RTX 3090 (eBay) | 2 × CompSniper’s $1,499 sold median (6 Oct 2026) = $2,998 in cards, before the rest of the PC |
| Want one card, lower power, less fuss | Used A6000 48GB (eBay) | Single-device 48 GB; simpler than multi-GPU |
| Quiet, efficient, or laptop; may go bigger later | 128GB+ Apple Silicon | Fits 70B with room; lowest power and noise |
| Want a turnkey NVIDIA appliance, not a parts list | DGX Spark (Amazon / Micro Center) | 128GB unified memory; CUDA/NVIDIA stack; not yet LocalRig-benchmarked |
| 70B only occasionally | Cloud A100/H100 (hourly) | Skip the capital outlay until local pays off |
Who This Is NOT For
- Anyone who has not done the fit math first. If you are unsure whether you even need 70B, start at the 7B/8B guide — most personal workloads are well served by an 8B or a 32B at a fraction of the cost and complexity.
- Single-GPU buyers hoping a 4090 will do it. A 70B does not fit in 24 GB at usable quality. If a single card is your hard limit, run a smaller model well rather than a 70B badly.
- People who need maximum tokens-per-second. 70B decode is bandwidth-bound and slower than smaller models on every consumer path here. If latency is the priority, a 32B-class model on a 24GB card will feel far snappier.
- Trainers and fine-tuners. This is an inference guide. Fine-tuning a 70B has very different (and much larger) memory requirements.
- Buyers who want exact throughput guarantees today. Until LocalRig publishes a first-party 70B benchmark, treat throughput as a range to verify on your own hardware, not a promise.
Sources
- LocalRig knowledge note, “GPU Memory Math for LLMs (2026)” — the VRAM ≈ params × bits/8 sizing model and the 70B size table.
- r/LocalLLaMA 70B benchmark and build threads (2024–2025) — community throughput ranges, explicitly not independently verified by LocalRig; a first-party 70B run is queued.
- NVIDIA RTX 3090 (24GB) and A6000 (48GB) product specifications, nvidia.com.
- Apple M2 Ultra (192GB) and M3/M4 Max (128GB) unified memory specifications, apple.com.
- NVIDIA DGX Spark Amazon listings B0FWJ16CCH (single unit) and B0GWK5MPJ5 (2-pack bundle), sold by Micro Center; product titles and ASINs fetched 2026-07-10.
- NVIDIA blog, 2026-10-02 and The Register, 2026-10-02: 64GB starting price and the reported 128GB list. Detail is on DGX Spark 64GB vs 128GB.
- CompSniper, RTX 3090, fetched 2026-10-06: sold median $1,499 across 204 eBay sales, typical range $1,329–$1,599, most recent sale 2026-10-06. The 2 × $1,499 = $2,998 pair figure on this page is arithmetic, not a sold bundle. The visible sample includes an RTX 3090 Ti row.
- RigPrice, RTX 3090, fetched 2026-10-06: used asking going rate $1,655 on the 2026-10-06 row; $1,665 on 2026-10-04. Asking prices, not sold prices.
- ComputingForGeeks, Josphat Mutai, updated 2026-10-03: Mac Studio M5 Max, 128GB, reported at $5,099 from Apple’s configurator that day. LocalRig did not re-open the configurator on 2026-10-06. The same figure is discussed on DGX Spark 64GB vs 128GB.
Frequently Asked Questions
How much VRAM does a 70B model need?
At Q4_K_M, plan on ~40 GB of weights plus KV cache — 46–48 GB is the comfortable floor. A single 24 GB or 32 GB card will not hold 70B Q4. That is a 48 GB (dual 3090 / used A6000) or 64 GB+ unified-memory Mac decision.
Can an RTX 5090 run Llama 70B at Q4?
Not at Q4 with a usable context. 32 GB is short of ~40 GB of weights. Q3 or aggressive offload will load it and feel slow. If 70B Q4 is the goal, skip the 5090 and buy 48 GB.
Is dual used 3090 cheaper than a Mac Studio for 70B?
On the cards alone, 2 × CompSniper's $1,499 sold median (6 October 2026) is $2,998 before shipping, a PSU, a board, and a case. That replaces this page's old $1,000–$1,600 pair band. It is not a dollars-per-gigabyte win: the pair is 48GB split, and a 128GB Mac is a larger pool. ComputingForGeeks reported a Mac Studio M5 Max 128GB at $5,099 on 3 October 2026; LocalRig did not re-open Apple's configurator on 6 October. The Mac still wins on silence. A full workstation can close the sticker gap.
When is cloud cheaper than buying 70B hardware?
Low or bursty hours. If you are not running the model most days, rent. Use the LocalRig rent-vs-buy calculator; it is not biased toward a hardware sale.